The LWE cryptosystem uses the following encryption formula: (where is a secret key, is a publicly known random vector picked per encryption, is a plaintext, is small noise randomly picked per encryption from a normal distribution, and is a ciphertext). is a scaling factor of the plaintext (shifting by bits to the left). Before encrypting the plaintext, we left-shift the plaintext several bits (i.e., bits) to secure sufficient space to store the error in the lower bits.
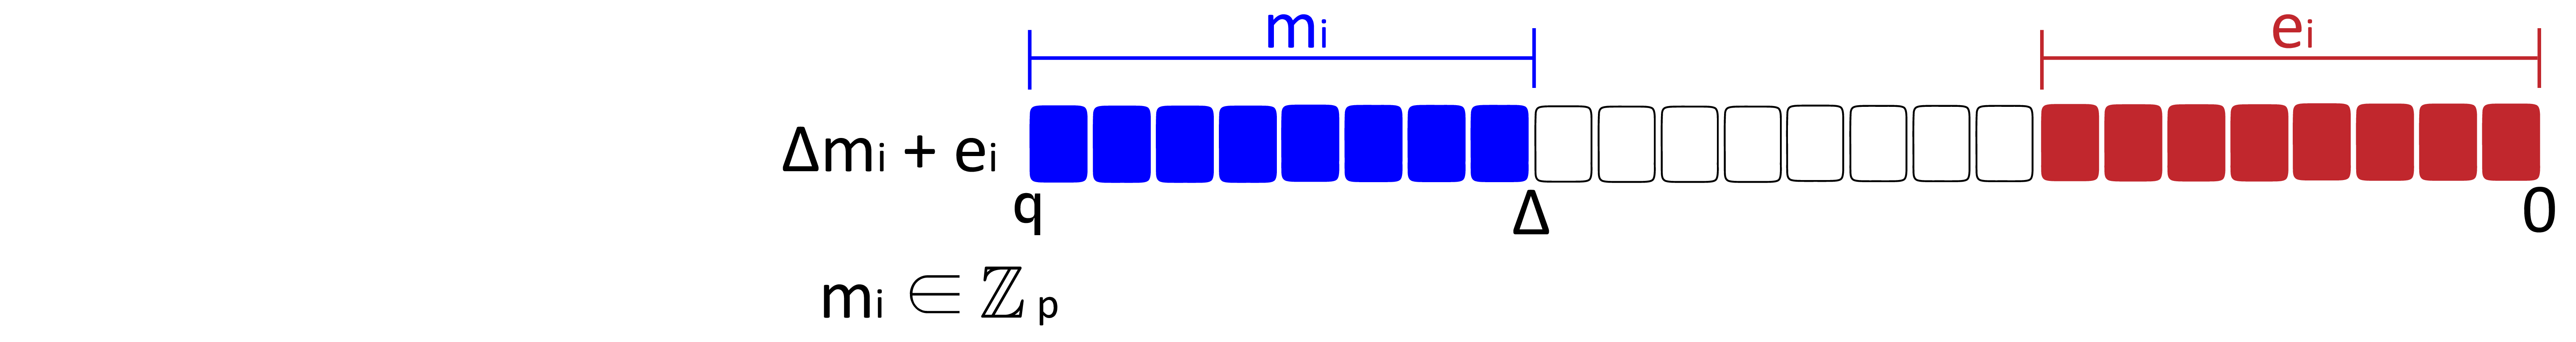
Figure 8 visually illustrates the term , where the plaintext left-shifted by bits and noised by the noise . The actual encryption and decryption formulas are as follows:
Summary B-1.2 Lattice-based LWE Cryptosystem
Encryption: , where and are publicly known also to the attacker, while are unknown (only known by the secret key owner).
means rounding the number to the nearest multiple of . For example, , which is rounding 16 to the nearest multiple of 10. As another example, , which rounds 17 to the nearest multiple of 8 (note that 17 is closer to 16 than to 24; thus, it is rounded to 16).
Correctness: In the decryption scheme, computing gives , which is Figure 8. Then, (i.e., rounding the value to the nearest multiple of ) gives , provided the added noise . That is, if the noise is less than , it will disappear during the rounding. Finally, right-shifting by bits gives . To summarize, if we ensure (which is why the noise should be smaller than this threshold), then we can eliminate during the decryption’s rounding process and retrieve the original . The reason we scaled by is to: (i) create space for storing in the lower bits during encryption such that the noise bits do not interfere with the plaintext bits (to avoid corrupting the plaintext bits); and (ii) blow away the noise stored in the lower bits during decryption without corrupting the plaintext .
Security: Given that an attacker has a large list of (i.e., many ciphertexts), it is almost impossible for them to derive , due to the random noise added in each encryption (which is a search-hard problem described in §B-1.1). This is because even small added unknown noises greatly change the mathematical solution for that satisfies all the equations.
Even in the case that the attacker has a large list of generated for the same ciphertext (where each ciphertext used different and to encrypt the same ), he still cannot derive , because a randomly picked different noise is used for every and is accumulated over ciphertexts, which exponentially complicates the difficulty of the linear algebra involved in solving . Also, in the actual cryptosystem (§B-2), the publicly known random vector and the secret key are not a single number but a long vector comprising many random numbers. Thus, adding to increases the entropy of randomness against the attack.
To summarize, lattice-based cryptography hides plaintext by adding the encryption component to it, along with a small random noise . During decryption, the secret key owner re-creates this encryption component by using her and removes it. She then removes the noise using the rounding technique and finally right-shifts the remaining by bits to get .